Synthetic Data for Enterprise AI: Generation, Privacy, Validation and Use Cases
⏱ 6 min read
By Sanjeet Mahajan Founder & CEO, Kizzy Consulting
Synthetic Data
AI Training Data
Digital Twins
Privacy & Governance
AI Training Data
Digital Twins
Privacy & Governance
Contents
hide
Executive Summary: What Is Synthetic Data?
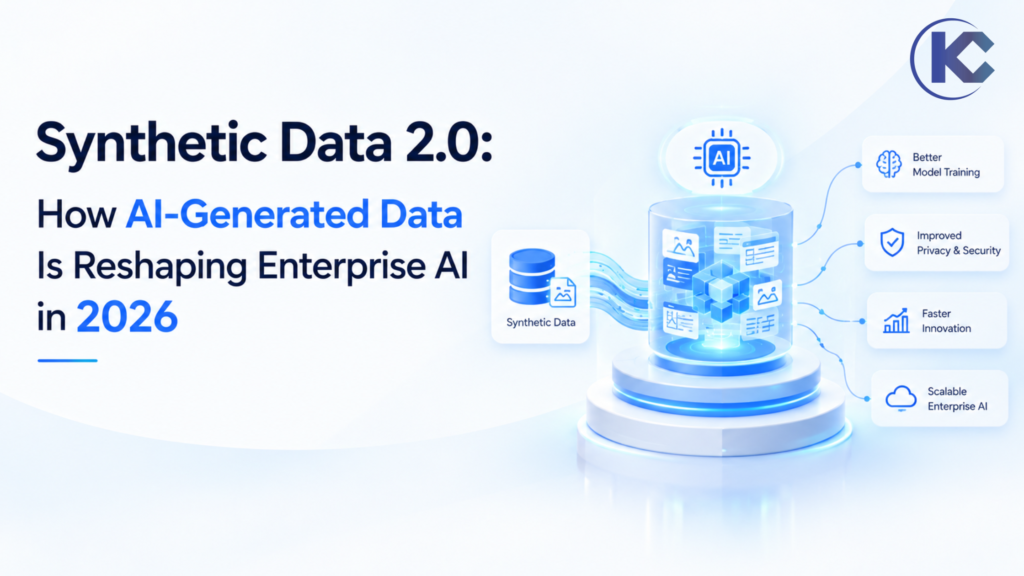
Synthetic data is artificially generated data designed to reproduce selected characteristics, relationships or behaviors of real-world data. It can include customer records, transactions, text, images, sensor readings and simulated events.
Organizations use it to develop and test models, generate rare scenarios, balance datasets and reduce routine dependence on production records. However, synthetic data still needs quality, privacy, bias and utility testing.
In this article, “Synthetic Data 2.0” is an editorial label for modern workflows that combine generative models, simulation, domain constraints, verification and governance. It is not presented as an established industry standard or a formally defined technical category.
1. What Is Synthetic Data?
Synthetic data is generated by statistical models, algorithms, simulations or AI systems rather than collected directly from real-world events. Depending on the method, a synthetic dataset may preserve selected statistical properties, relationships, labels or behaviors of a source population.
It is useful when teams need more examples, controlled test scenarios or datasets for development environments. It should not automatically be treated as an exact substitute for real-world observations.
Structured Records
Artificial customer profiles, accounts, transactions, claims, product records and operational data.
Synthetic Text
Generated conversations, support tickets, documents, contracts and domain-specific examples.
Synthetic Images
Artificial visual examples for inspection, computer vision and rare-scene testing.
Time-Series Data
Simulated sensor readings, telemetry, demand patterns, financial signals and IoT events.
Important distinction: A dataset can look realistic while still being statistically inaccurate, biased, unrepresentative or unsuitable for its intended task. Evaluate the dataset against its intended use, not appearance alone.
2. Modern Synthetic-Data Workflows: From Generation to Verification
Older approaches include statistical sampling, rule-based generation and methods such as SMOTE and generative adversarial networks (GANs). Modern pipelines can combine these methods with foundation models, domain constraints, simulators and automated validation.
The term “Synthetic Data 2.0” is used here as shorthand for this broader workflow approach, not as a universally recognized product category, standard or new algorithm. The underlying methods are established areas of research and engineering; the combination depends on the problem being solved.
The shift: from more data to fit-for-purpose data
A useful workflow begins with a defined objective – for example, testing fraud detection, validating an AI agent, evaluating document extraction or simulating equipment failure. It then generates relevant examples and measures whether they improve the intended system.
1. Generation
Create records, text, images or scenarios using a suitable model or simulator.
Create records, text, images or scenarios using a suitable model or simulator.
2. Constraints
Apply domain rules, valid ranges, relationships and business logic.
Apply domain rules, valid ranges, relationships and business logic.
3. Verification
Check correctness, diversity, duplication, privacy risk and task utility.
Check correctness, diversity, duplication, privacy risk and task utility.
4. Evaluation
Test the resulting model or application against held-out data and real-world criteria.
Test the resulting model or application against held-out data and real-world criteria.
3. Why Enterprises Use Synthetic Data
Organizations often face data-access restrictions, limited examples of rare events, inconsistent labels or the cost of repeatedly preparing production data for development. Synthetic data can help, provided the resulting dataset is validated and appropriate for the task.
Privacy-Aware Development
Synthetic records can reduce routine exposure to production data in development and testing. They do not eliminate privacy risk automatically.
Rare-Event Coverage
Create controlled examples of uncommon fraud patterns, equipment failures, unusual customer behavior or rare visual conditions.
Repeatable Testing
Build repeatable datasets for software QA, integration testing, AI evaluation and regression testing.
Coverage and Balance
Generate targeted examples for underrepresented classes or missing operating conditions, then check for introduced bias.
The data-supply problem is also a data-quality problem
Having more data does not guarantee better AI. Data must be relevant, correctly labeled, diverse, representative, legally usable and aligned with the situations a system will encounter. Enterprise data may also be spread across CRM systems, ERP platforms, data warehouses and private repositories.
Before generating new data, organizations should identify which limitation they are trying to solve: insufficient volume, missing scenarios, low-quality labels, restricted access or a lack of reliable evaluation examples.
Related reading:
AI Readiness Assessment 2026 – assess whether your data, infrastructure, workflows and governance are prepared for enterprise AI.
4. Digital Twins and Synthetic Data Use Cases
A digital twin is a virtual representation of a physical asset, process, environment or system. Synthetic data can provide additional scenarios for testing how the represented system might behave under different conditions.
Real World
Measurements and events
Measurements and events
Digital Twin
Virtual system model
Virtual system model
Synthetic Scenarios
Controlled what-if tests
Controlled what-if tests
| Industry | Example Data | Potential Objective |
|---|---|---|
| Financial Services | Synthetic transactions and fraud patterns | Test fraud and risk models |
| Healthcare | Artificial patient records and clinical scenarios | Support controlled research and development |
| Manufacturing | Sensor readings and equipment-failure scenarios | Test predictive maintenance models |
| Automotive | Rare driving and road scenarios | Expand simulation-based safety testing |
| Retail | Customer behavior and demand scenarios | Test forecasting and personalization |
| Cybersecurity | Synthetic attack and anomaly patterns | Stress-test detection and response systems |
Synthetic examples are particularly useful when real events are expensive, rare or unsafe to reproduce. For safety-critical use cases, simulated results still need appropriate real-world validation.
5. Synthetic Data Generation Methods Compared
The best method depends on the data type, the task, the level of fidelity required and the checks available to validate the output.
| Method | Typical Fit | Key Control | Limitation |
|---|---|---|---|
| SMOTE | Class imbalance in selected tabular ML tasks | Validate class boundaries and downstream metrics | Not a general-purpose text or image generator |
| GANs | Learning to generate examples resembling a training distribution | Fidelity, diversity and mode coverage | Training instability or limited diversity |
| Generative Models | Text, records, images and task-specific examples | Factuality, safety, diversity and privacy checks | Hallucination, duplication and source-data memorization |
| Simulation | Industrial processes, robotics and digital twins | Model assumptions and real-world comparison | Simulation-to-reality gap |
| Rules and Templates | Predictable formats, workflow testing and boundary conditions | Coverage and rule consistency | May miss natural variation and unexpected behavior |
For example, SMOTE may help address class imbalance in a tabular classification task, but it is not a replacement for a simulation platform or a generative model. Teams should select methods based on the problem and validate performance using appropriate holdout data.
6. Synthetic Data for AI Training and Verification
Synthetic examples can be used to train or fine-tune selected models, improve coverage of rare cases, create test datasets and evaluate application behavior. In self-play approaches, a model may generate multiple candidate solutions and an external evaluator can determine which candidates meet defined criteria.
This is most effective when outputs can be checked against reliable rules, tests, simulators or expert review. A model’s confidence in an answer is not, by itself, evidence that the answer is correct.
A practical synthetic-data quality loop
- Define the target capability, business scenario or evaluation question.
- Generate examples using a suitable model, simulator or rule set.
- Validate examples using domain rules, tests, external checks or expert review.
- Remove duplicates, invalid records and unsafe or low-quality outputs.
- Assess coverage, fidelity, bias and privacy risks.
- Train or test the system using the approved dataset.
- Measure results against independent holdout data and relevant real-world outcomes.
A note on retrieval-augmented generation (RAG)
For RAG applications, synthetic question-answer pairs can help test retrieval coverage, citation behavior and response quality. The generated questions and expected answers should be checked against trusted source documents. Synthetic evaluation sets should not be the only measure of whether a RAG system works for real users.
Related reading:
AI Integration and Implementation Services – connect AI applications with enterprise systems, data and workflows.
7. Model Collapse: Why More Synthetic Data Is Not Always Better
Model collapse describes degradation that can occur when models are trained recursively on generated data, potentially causing parts of the original data distribution – including rare patterns – to disappear over successive generations.
A 2024 paper in Nature, “AI models collapse when trained on recursively generated data”, examined this effect across several types of generative models. The authors highlighted the importance of preserving access to original data distributions. The research identifies a real risk, not proof that every use of synthetic data causes model collapse.
Trusted Data
Real-world diversity
Real-world diversity
Model
Learns patterns
Learns patterns
Generated Data
New examples
New examples
Next Iteration
Risk of distribution loss if unmanaged
Risk of distribution loss if unmanaged
The answer is not to avoid synthetic data entirely. Instead, maintain appropriate connections to trusted source data, monitor provenance, preserve diversity, verify generated examples and evaluate systems on independent data that was not generated by the same pipeline.
8. Privacy, Governance and Validation
Is synthetic data automatically private? No. A model may memorize source records or generate examples that reveal sensitive information. Privacy risk depends on the source data, generation method, model behavior, access controls and testing performed.
The NIST Special Publication 800-226, Guidelines for Evaluating Differential Privacy Guarantees, published in March 2025, explains how to assess differential privacy and the hazards that can arise when privacy claims are evaluated incorrectly. NIST distinguishes formal differential-privacy guarantees from informal claims of privacy protection. Not every synthetic-data method provides differential privacy.
Correctness
Do examples satisfy the rules and requirements of the intended task?
Fidelity and Coverage
Does the dataset preserve the important properties and cover relevant scenarios?
Privacy
Could records reveal or reproduce information about people in the source dataset?
Bias and Utility
Does the data amplify bias or improve performance on the intended task?
For enterprise use, establish data ownership, approved purposes, access rules, retention periods, provenance tracking and review responsibilities. For sensitive data, involve security, privacy and legal specialists before approving the dataset for production use.
Related reading:
AI Operations and Governance – explore governance controls, risk routing, observability and oversight for enterprise AI systems.
9. Synthetic Data vs. Anonymized Data
These approaches are related but not interchangeable. Synthetic data is generated, while anonymized data is derived from real records that have been transformed to reduce the ability to identify individuals. The actual privacy protection depends on how each dataset is created and evaluated.
| Factor | Synthetic Data | Anonymized Data |
|---|---|---|
| Creation | Generated by a model, algorithm or simulator | Derived from real records after transformation |
| Record origin | Intended to represent artificial examples | Starts with observations about real people or events |
| Privacy risk | Can remain vulnerable to memorization or disclosure | Depends on re-identification risk and transformation quality |
| Potential uses | Simulation, testing, model development and rare scenarios | Analysis and sharing where transformed real data is suitable |
Neither label alone proves that a dataset is safe to share. Organizations should assess the threat model, sensitivity of the original records and applicable legal requirements before approving use.
Build a Data Foundation for Enterprise AI
Synthetic data delivers value when it supports a clear data strategy. Connect data quality, integration, security, governance and evaluation before scaling AI into business-critical workflows.
10. Enterprise Implementation Example: Testing an AI Support Agent
The following is an illustrative workflow, not a verified Kizzy client case study or measured customer result. It shows how an enterprise might use synthetic data to test an AI support agent before connecting it to production systems.
Illustrative use case
5 test categories
5 test categories
A team wants to validate whether an AI agent can answer account questions, classify support requests, follow business policies and route uncertain cases to a human.
- Create synthetic customer profiles: use fictional names, account states and product scenarios rather than copied production identities.
- Generate support conversations: include routine questions, incomplete requests, conflicting details and unusual cases.
- Define expected outcomes: document correct classifications, permitted actions, escalation triggers and policy-based answers.
- Run evaluation tests: measure routing accuracy, policy compliance, unsupported claims and correct escalation behavior.
- Validate independently: compare the results with human-reviewed cases and a separate holdout dataset before deployment.
What should the team measure?
Use a defined evaluation set and report actual results rather than assumed improvements. Relevant measures may include classification accuracy, policy adherence, successful task completion, escalation precision, privacy leakage findings and failure rates across scenario types.
For a credible case study, record the baseline, dataset size, test methodology, evaluation period and post-change result. Without those details, a numerical performance claim should not be presented as a verified business outcome.
11. A Practical Roadmap for Enterprise Adoption
Start with a bounded use case and measurable acceptance criteria. Expand the workflow only after the dataset has demonstrated value and passed appropriate privacy and quality checks.
STEP 1
Define the Objective
Identify the model, application or workflow that needs better training, testing or evaluation data.
STEP 2
Choose the Method
Select rules, statistical methods, generative models or simulation based on the problem.
STEP 3
Validate the Dataset
Test quality, diversity, privacy risk, representativeness and suitability for the task.
STEP 4
Evaluate and Govern
Compare results with independent data, document limitations and assign review ownership.
Before scaling, ensure the process has a clear owner, repeatable generation steps, versioned datasets, traceable sources, access controls and a plan for monitoring quality as the underlying business or environment changes.
Related reading:
Enterprise AI Readiness Assessment – identify data, technology and governance gaps before scaling an AI initiative.
12. Synthetic Data FAQs
What is synthetic data?
Synthetic data is artificially generated data designed to reproduce selected properties, relationships or behaviors of real-world data. It can be created using statistical methods, simulations, machine learning models or generative AI.
What does Synthetic Data 2.0 mean?
In this article, Synthetic Data 2.0 is an editorial label for modern workflows that combine generation with domain constraints, verification, evaluation and governance. It is not presented as an established industry standard or a universally defined technical term.
Is synthetic data better than real data?
They serve different purposes. Synthetic data can add controlled examples and rare scenarios, while real-world data remains important for grounding systems and evaluating whether they work in actual operating conditions.
Is synthetic data completely private?
No. Privacy depends on the generation method, source data, model behavior and controls. Some approaches provide formal differential-privacy guarantees; ordinary synthetic generation does not automatically provide them.
What is model collapse?
Model collapse is degradation that can occur when models are recursively trained on generated data, potentially reducing diversity and losing information about less common patterns in the original distribution.
How do organizations validate synthetic data?
They can evaluate statistical fidelity, diversity, coverage, duplicate rates, privacy risk, bias and downstream model performance. Independent holdout data and domain-expert review help establish whether the dataset is fit for purpose.
Can synthetic data help test AI agents?
Yes. It can provide repeatable test cases for classification, tool use, workflow routing, policy compliance and edge cases. Expected outcomes should be verified, and agent performance should also be tested against independent scenarios representative of real use.
Sources and Further Reading
- Shumailov et al., “AI models collapse when trained on recursively generated data,” Nature (2024).
- National Institute of Standards and Technology, SP 800-226: Guidelines for Evaluating Differential Privacy Guarantees (2025).
- Kizzy Consulting, AI Readiness Assessment 2026.
- Kizzy Consulting, AI Operations and Governance.
- Kizzy Consulting, Data Foundation for AI.
External research supports the technical discussion. The illustrative enterprise workflow in this article is an example for explanation and is not a claim of measured customer results.
Build a Data Foundation for Enterprise AI
Explore how data quality, integration, governance and evaluation can support more reliable enterprise AI systems with Kizzy Consulting.
Discuss Your AI Data Strategy
Talk to Kizzy Consulting about data foundations, AI readiness, governance and enterprise AI implementation.